
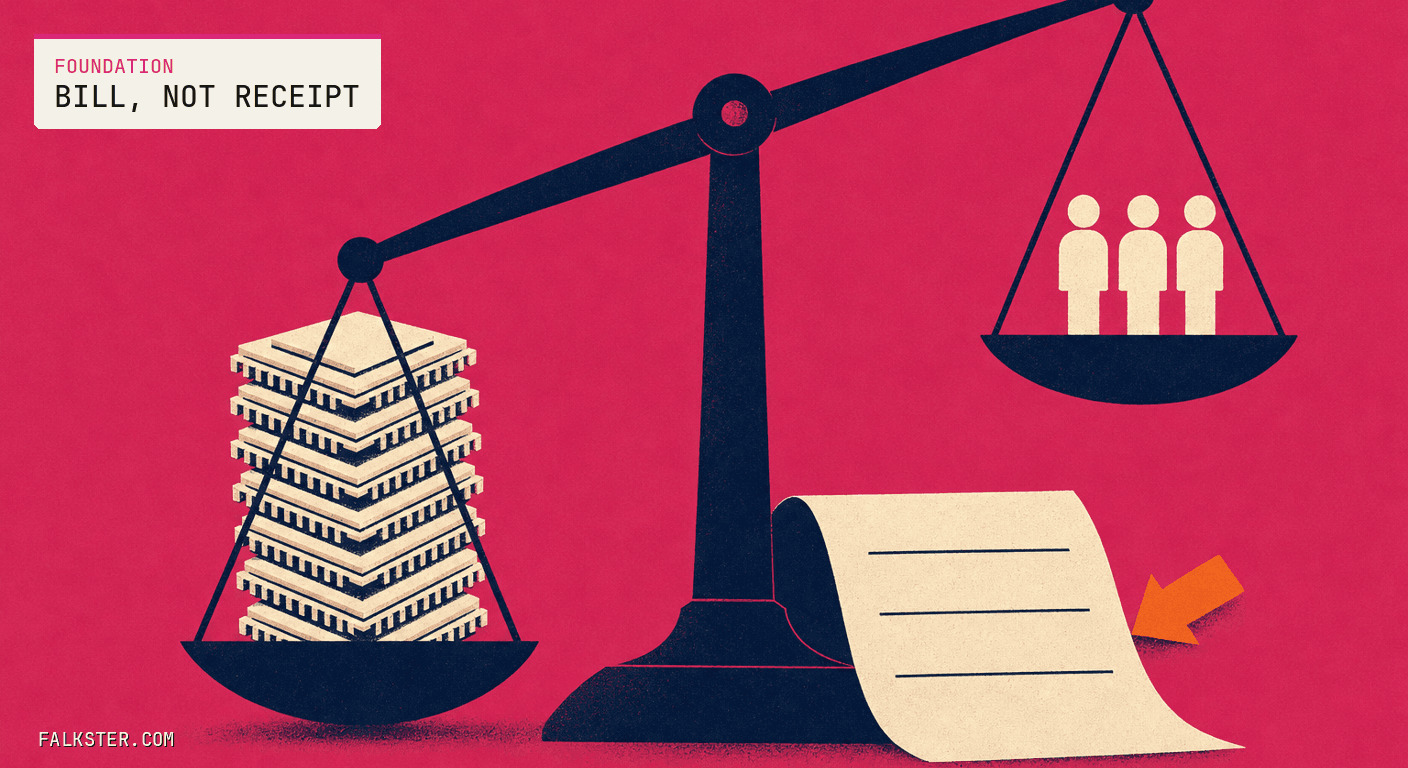
Mercor's Series D came with a line about its own spending that other founders are going to repeat: the company spends three times as much on inference as on employee salaries. This is a Ship Story. The decision under that line is a good one, and the ratio itself is the wrong thing to carry away from it.
The short version
- Mercor raised a $750M Series D at a $20B valuation on November 10, 2026, double the $10B at which it raised $350M in October 2025, as The Next Web reported. swyx's AINews of November 11 gives the revenue line: a $1B run rate in February, $2B in June, and $3B annualized now.
- The announcement says Mercor spends 3x as much on inference as on employee salaries, that this pays for itself by making the team better at their jobs, and that if the ratio held across the economy it would point to near double-digit GDP growth.
- The decision behind it, keep hiring and buy compute per employee, is worth copying. The ratio is not a result. It divides one cost by another, the largest cost sits outside it, and no output number comes with it.
- I built 39 agents in 80 days, paid inference on all of them, and 13 ended with zero references anywhere else in the system.
- Under an inference-to-salary ratio, report the share of runs something downstream used, the hours spent reviewing, and tokens per finished unit of work.
The decision and the result
Mercor pays experts to train and evaluate AI models. The Next Web puts the network at more than five million of them.
The numbers, with who reported each. The Next Web, November 10: a $750M Series D at $20B, twice the $10B valuation of October 2025, when the company raised $350M. swyx in AINews, November 11: the Series C came when revenue was under $500M, the run rate crossed $1B in February and $2B in June, and it is now $3B annualized.
The line about spending is from the announcement, as AINews quotes it and The Next Web attributes to co-founder Brendan Foody's blog post. I have not opened that post myself. Mercor spends 3x as much on inference as on employee salaries. It says the spend pays for itself by making the team better at their jobs. And it extends the thought: if that ratio held as AI spreads through the economy, it would point to something close to double-digit GDP growth over five years.
RuntimeWire reported in September that Foody had first posted the 3x figure then, with a framing I find more interesting than the ratio. The compute produces enough value that Mercor keeps hiring instead of using AI to shrink.
That is the decision. Many of the AI headcount stories this year run the other way, with fewer people and the savings booked. Mercor kept adding people and bought each of them a large compute budget. From February to November the run rate tripled.
What the ratio leaves out
I would copy the decision. I would not put the ratio on a slide as evidence that it worked, for three reasons.
It divides one cost by another. Inference over salaries tells you where the money went. A company can triple that ratio by wasting tokens.
The largest cost is outside it. The same RuntimeWire report says payouts to Mercor's experts ran above $4M a day in September and were not part of the comparison. More than $4M a day is more than $1.4B a year by my arithmetic, and it is a cost of doing the work that the ratio does not touch. So the ratio describes the staff, not the whole of how the work gets done.
"Pays for itself" has no number next to it. It may well be true. A run rate that triples in nine months is not nothing. But the claim is about output per person, and what was published is two inputs.
My small version
I have run this experiment at a scale where I could count every piece.
In Twenty Minutes Is Not a Reason to Build I wrote that I built 39 agents in 80 days. Each one was cheap, so each one got a yes. When I audited them, in 39 PM AI Agents Deployed: What Stuck, What Died, and Why, 13 of the 39 had zero references from anywhere else in the system. No handbook chapter, no other post, and no landing page depended on them.
13 of 39
I paid inference on all 39. If I had reported my token spend against any labor number in April, it would have looked like a company leaning into AI. A third of the agents were being read by nothing.
The other missing line is review. In SaaStr Runs $20M on 3 Humans and 20 Agents. Revenue per Human Hides the 13-Hour Review Day. I looked at Jason Lemkin's figure of about $6.7M in revenue per human, next to his own account of a 13-hour day spent entirely on reviewing and fixing agent work. Inference-to-salary has the same blind spot from the other side. It counts what the models cost and not what it cost people to check them.
The receipt
Inference-to-salary is going to be on board slides next year. It is easy to compute and it sounds like commitment. When it shows up, I would ask for three lines under it.
- Share of runs used. Of the agent runs you paid for, how many produced something another system or person consumed. Mine was 26 of 39 agents with anything depending on them, and it took an audit to learn it.
- Reviewed hours. How many hours a week people spend checking agent output, by agent.
- Tokens per finished unit. Pick the unit the business sells or ships, and divide.
Mercor may have all three and good answers. The announcement did not include them, and the GDP sentence needs them, because an economy that triples its inference bill has only spent money so far.
This week
Take last month's inference bill and split it by what the runs fed. Anything that fed nothing goes in its own row. That row is the first thing to show next to the ratio. This sits in Building a Company in Public because the count behind it is my own wrong calls.
Related answer: Is inference spend per employee a good AI metric?
Sources: swyx, "[AINews] Mercor $750m Series D at $20B valuation, $3B run rate," Latent Space, November 11, 2026, lead item read in full: the run-rate milestones, the under $500M at Series C, and the quoted announcement. The Next Web, "Mercor raises $750m at a $20bn valuation to train AI on every job," November 10, 2026: the round, the valuation, the October 2025 round, and the five million experts. RuntimeWire, "Mercor spends 3X employee salaries on LLM inference, CEO says," September 13, 2026: the earlier post and the $4M a day in expert payouts. I did not open Brendan Foody's own posts. The 39, 80, 13, and 26 are my own, and the $6.7M and 13 hours are Jason Lemkin's, from the posts linked above.
Frequently asked
What did Mercor announce in November 2026?+
A $750M Series D at a $20B valuation on November 10, 2026, double the $10B at which it raised $350M in October 2025, as The Next Web reported. swyx's AINews adds that the run rate crossed $1B in February and $2B in June and is now $3B annualized. I have not opened Mercor's own announcement.
What is the 3x inference-to-salary ratio?+
Mercor says it spends 3x as much on inference as on employee salaries, that the spend pays for itself by making the team better at their jobs, and that if the ratio held across the economy it would point to near double-digit GDP growth. The line is from the announcement as AINews quotes it. RuntimeWire reported that co-founder Brendan Foody first posted the figure in September.
Why is the ratio not a result?+
It divides one cost by another, so it shows where money went and not what came back. RuntimeWire reported that payouts to Mercor's experts, above $4M a day in September, are outside the comparison. And the claim that it pays for itself was published without an output figure.
What is worth copying from Mercor?+
The decision. As RuntimeWire describes Foody's framing, the compute produces enough value that the company keeps hiring instead of using AI to shrink. It added people and gave each a large compute budget, and the run rate tripled between February and November as AINews reports it.
What is your own evidence?+
I built 39 agents in 80 days. Each was cheap, so each got a yes. When I audited them, 13 had zero references from anywhere else in the system, and I had paid inference on all 39. A ratio of my token spend to any labor number would have looked like progress while a third of the agents were read by nothing.
What should be reported under an inference-to-salary ratio?+
Three lines. The share of paid runs that produced something another system or person used; mine was 26 of 39 agents with anything depending on them. The hours per week people spend reviewing agent output, by agent. And tokens per finished unit of whatever the business ships.
Sign in with LinkedIn to leave a comment.
Sign in with LinkedIn